Nvidia releases open-weight Nemotron 3.5 speech model and Granary v2 dataset
Nvidia has launched Nemotron 3.5 Transcribe, a free, open-weight speech model supporting 40 languages alongside its Granary v2 training corpus of over 460,000 audio hours.
Nvidia has launched Nemotron 3.5 Transcribe, also referred to as Nemotron 3.5 ASR, an open-weight artificial intelligence model for multilingual transcription and translation. Released alongside Granary v2, an open-source training dataset containing 463,062 hours of speech across 48 languages, the model is designed to process recorded audio files rather than real-time live streams.[2][4][5][6][7]
The model contains roughly 30 to 34 billion total parameters, with approximately 4 billion to 4.3 billion active per token or step. According to launch materials, it can operate on a single chip, spanning from Jetson boards to Blackwell GPUs, and accommodates audio recordings up to one hour long. Because it focuses on pre-recorded files, TechCrunch reported that the tool is positioned for meeting and medical documentation rather than live audio streaming.[3][5][6][7]
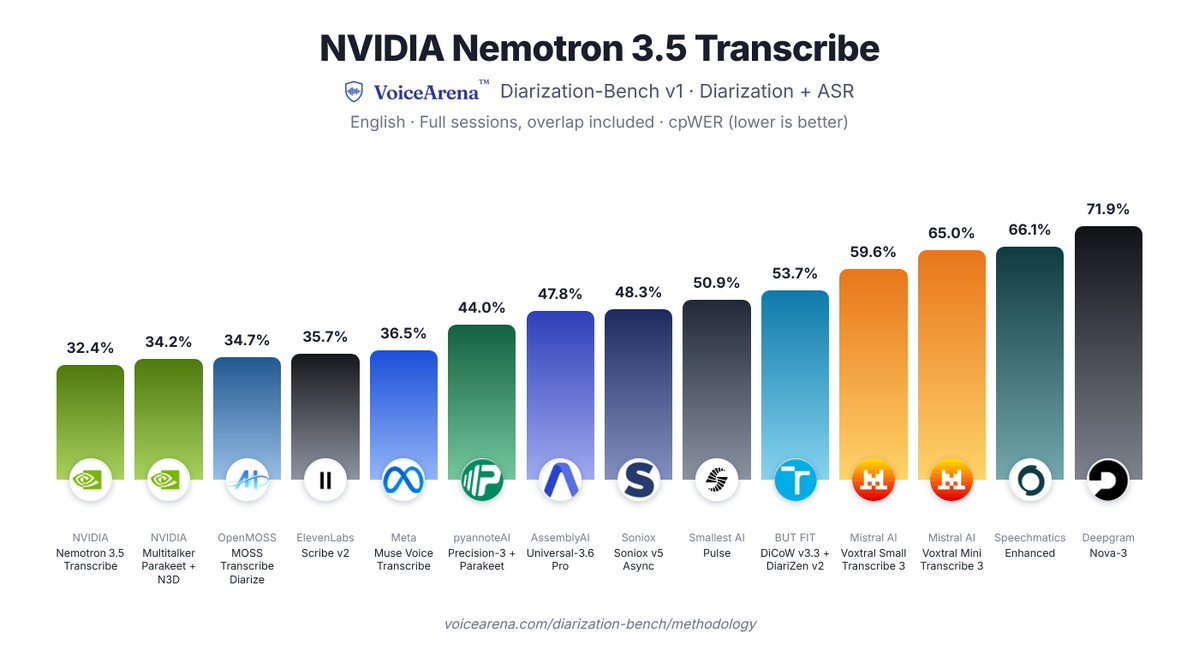
Nemotron 3.5 Transcribe transcribes up to 40 languages and translates between English and 31 languages. It is promptable, allowing users to provide names and technical vocabulary before processing or ask questions about the audio via an English-trained Q&A feature. The model also performs speaker diarization for up to eight individuals across 13 languages, tracking speakers even when they speak simultaneously. Nvidia reported that the system tops Hugging Face's open English speech recognition leaderboard with a 5.33% average word error rate and led VoiceArena's 14-system Diarization-Bench v1 evaluation with a 32.4% concatenated minimum-permutation word error rate.[1][3][5][7][8]
Key facts
- Nvidia released Nemotron 3.5 Transcribe as a free, open-weight speech model alongside Granary v2, an open-source dataset spanning 463,062 hours of speech in 48 languages.
- The model transcribes up to 40 languages and translates between English and 31 languages for audio recordings up to one hour in length.
- Nemotron 3.5 Transcribe works exclusively on recorded audio and does not support live streaming audio.
- The architecture features roughly 30 to 34 billion total parameters, with about 4 billion to 4.3 billion active per token or step.
- The model can differentiate up to eight speakers across 13 languages, including when speech overlaps, and led VoiceArena's Diarization-Bench v1 test with a 32.4% cpWER score.
- Nvidia reported a 5.33% average English word error rate, placing the model at the top of Hugging Face's open speech recognition leaderboard.
Sources · 7 sources
- TN
The New Stack@thenewstackPost on X ·
Nvidia’s new open-weight Nemotron 3.5 Transcribe takes instructions before it listens and tops Hugging Face’s English speech recognition leaderboard. https://t.co/kuQsyJgYtJ
Open source - TE
TechmemeArticle ·
Nvidia debuts Nemotron 3.5 Transcribe, an open-weight model for multilingual audio transcription and translation, and Granary v2, its open-source speech dataset (Kyt Dotson/SiliconANGLE) Kyt Dotson / SiliconANGLE : Nvidia debuts Nemotron 3.5 Transcribe, an open-weight model for multilingual audio transcription and translation, and Granary v2, its open-source speech dataset — Nvidia Corp. today released a leaderboard-winning open artificial intelligence model for multilingual audio transcription and translation …
Open source - WS
Wall St Engine@wallstenginePost on X ·
NVIDIA JUST RELEASED NEMOTRON 3.5 TRANSCRIBE 40 languages. ~4.3B active parameters. Open weights. $NVDA reports #1 among open-weight models on Hugging Face’s English transcription leaderboard. Watch it track who said what, even when speakers talk over each other. https://t.co/JU68mPUwR3
Open source - CB
Crypto BriefingArticle ·
Nvidia releases Nemotron 3.5 ASR, a free open-weight model for 40-language audio transcription Nvidia's Nemotron 3.5 ASR democratizes multilingual audio transcription, potentially transforming global communication and accessibility. The post Nvidia releases Nemotron 3.5 ASR, a free open-weight model for 40-language audio transcription appeared first on Crypto Briefing .
Open source - CH
Chubby♨️@kimmonismusPost on X ·
NVIDIA is releasing an open speech model that can transcribe a meeting, label who said what, translate it and answer questions about the recording: Nemotron 3.5 Transcribe supports: - Transcription in 40 languages - Translation between English and 31 languages - Up to eight speakers, with speaker labels in 13 languages - Recordings up to an hour long You can give it names and technical terms to guide the transcript, or ask questions about the audio. Audio Q&A is trained in English. It has roughly 30B parameters, with about 4B active per token, and can run on your own NVIDIA GPU. According to NVIDIA's launch materials, it ranks first among open-weight models on Hugging Face's English Open ASR leaderboard and leads VoiceArena's 14-system test of transcription with speaker attribution. Built for recorded audio. Live streaming uses a separate model. Super cool to see! Model: https://t.co/jEe0LRZoqg Demo: https://t.co/xIr5mf0PCV Blog: https://t.co/mQk95Waudq
Open source - TE
TechCrunch@TechCrunchPost on X ·
Nvidia just released a free speech-to-text model that can transcribe up to 40 languages, but it only works on recordings, not live audio, so it’s a big step for meeting and medical transcription tools while still leaving real-time use to rivals like https://t.co/58l5TUPMsl
Open source - TA
Techstrong.ai@TechstrongaiPost on X ·
NVIDIA on Wednesday launched Nemotron 3.5 Transcribe, a free, open-weight model that transcribes speech across 40 languages and translates 31 of them to and from English, shipping alongside Granary v2, a training corpus of 463,062 hours of speech in 48 languages. With roughly 30 to 34 billion total parameters but only about 4 billion active per step, it runs on a single chip from Jetson boards to Blackwell GPUs, and NVIDIA claims a 5.33% average English word error rate at the top of Hugging Face's open speech-recognition benchmark. See what the release means for enterprise voice and clinical transcription deployments: https://t.co/OIQObb9Eoc #NVIDIA #AI #SpeechRecognition #OpenWeights #EnterpriseAI
Open source - TN
The New Stack@thenewstackPost on X ·
Nvidia launches a promptable transcription model https://t.co/WTYfGvP9zL
Open source