Alibaba launches Qwen4-Max flagship model with cheaper API pricing and improved benchmark scores
Alibaba has released Qwen4-Max, its 2.4-trillion-parameter mixture-of-experts flagship model featuring native vision, a 1-million-token context window, and lower API pricing, with independent evaluations showing efficiency gains over its predecessor.
Alibaba has introduced Qwen4-Max, its latest flagship artificial intelligence model built on a mixture-of-experts architecture. The model features 2.4 trillion backbone parameters, activates 71 billion parameters per token, and incorporates 328 billion additional N-gram embedding parameters alongside native vision capabilities and a 1-million-token context window. Alibaba claims the model outperforms Qwen3.8-Max while requiring up to roughly 50% fewer tokens, reducing average task costs by over 60% in internal Work360 testing.[3][4][5][10][11]
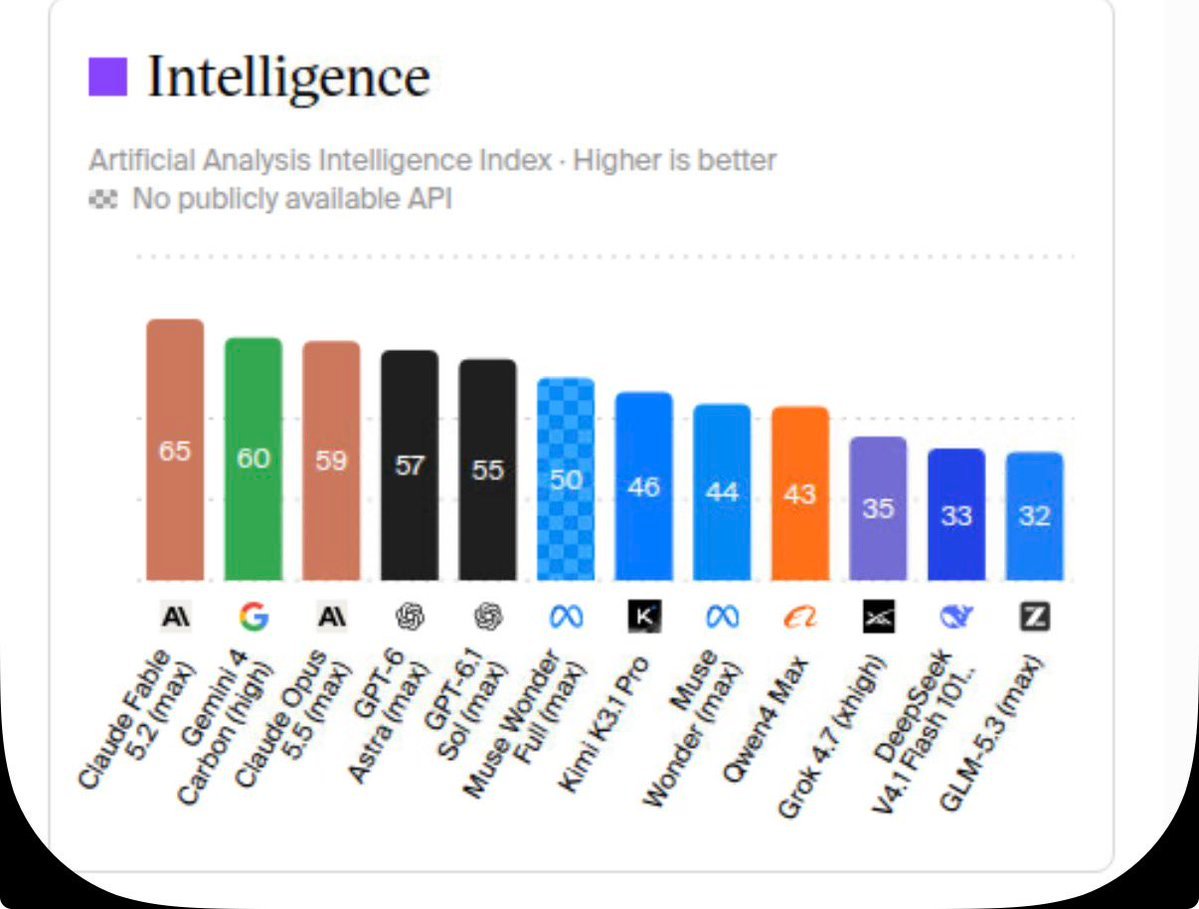
Independent evaluation by Artificial Analysis placed Qwen4-Max at 43 on its Intelligence Index under extra-high reasoning effort, representing a 9-point increase over Qwen3.8-Max (34) and trailing Moonshot's Kimi K3.1 Pro (46). Artificial Analysis calculated Qwen4-Max's cost per task at $3.27—roughly three times less than Qwen3.8-Max's $10.02 and about 11% below Kimi K3.1 Pro ($3.68)—owing to lower token consumption and reduced pricing. In task-level evaluations, Qwen4-Max led Kimi K3.1 Pro in agentic business file workflows on AA-Briefcase (1686 versus 1674 Elo), but lagged behind it on Terminal-Bench 4.0 (48% versus 67%) and matched it on FrontierCode 2.0 at 26%, where Tencent Hy4 scored 31%.[2][9]
Alibaba has made Qwen4-Max available exclusively via API on QwenCloud, alongside previews on Qwen Studio, QwenWork, and Qoder, rather than offering open model weights. API usage is priced at $1.50 per million input tokens, $4.50 per million output tokens, and $0.075 per million implicit cached tokens, representing a 70% decrease in cache pricing compared to Qwen3.8-Max. Alibaba stated that while the flagship Max model remains closed, it plans to release open weights for smaller upcoming models in the Qwen4 family.[1][3][4][5][6][7][8]
Key facts
- Qwen4-Max is a mixture-of-experts model featuring 2.4 trillion backbone parameters, 71 billion activated parameters per token, native vision, and a 1-million-token context window.
- Artificial Analysis evaluated Qwen4-Max at 43 on its Intelligence Index using extra-high reasoning effort, 9 points higher than Qwen3.8-Max (34) and 3 points below Kimi K3.1 Pro (46).
- Artificial Analysis measured Qwen4-Max's cost per Intelligence Index task at $3.27, roughly one-third of Qwen3.8-Max ($10.02) and about 11% less than Kimi K3.1 Pro ($3.68).
- Qwen4-Max consumes about 105,000 output tokens per Intelligence Index task, 39% fewer than Qwen3.8-Max's roughly 171,000.
- First-party API pricing for Qwen4-Max is set at $1.50 per million input tokens, $4.50 per million output tokens, and $0.075 per million implicit cached tokens.
- Qwen4-Max is offered only through API access without open model weights, though Alibaba announced plans to release open weights for smaller Qwen4 models.
Sources · 9 sources
- DE
Decrypt@DecryptMediaPost on X ·
Alibaba Launches Qwen4-Max With a 1 Million-Token Context Window and Lower Prices. Alibaba's Qwen team said at 9:01 PM EST Sunday that Qwen4-Max costs $1.50 per million input tokens and $4.50 per million output tokens, both lower than Qwen3.8-Max. https://t.co/gFBUk3y1Wj
Open source - 王小
王小波@wanxuboPost on X ·
Qwen 4 max 发布 正式跻身 中国模型第二🥳 我还以为他要打 fable , 没想到跑分一般😂 https://t.co/SeSkSTzuzi
Open source - QW
Qwen@Alibaba_QwenPost on X ·
📢 Meet Qwen4-Max, your new AI teammate for work, creativity, and discovery! Qwen4-Max is built on a new MoE architecture with native vision and a 1M-token context window. Highlights: - Outperforms Qwen3.8-Max with up to ~50% fewer tokens, while average cost per task drops over 60% in our internal evaluation. - Advances real-world productivity through greater proficiency with professional tools, stronger long-horizon execution, and higher-quality deliverables. - Handles real tasks, including 3D modeling, game development, manufacturing, finance, law, healthcare, and frontier scientific discovery. - $1.5/M tokens for input, $4.5/M tokens for output, and $0.075/M tokens for implicit caching — all lower than Qwen3.8-Max, with implicit caching down by 70%. The API is live on QwenCloud. You can also try Qwen4-Max on Qwen Studio, QwenWork and Qoder. Start building today! 🚀 - Blog: https://t.co/AuiWxugjE6 - API: https://t.co/aS1QEkS8nu - Token Plan: https://t.co/YRvcGdB9Bv More to come! The open weights of smaller Qwen4 models will be released. Stay tuned. 👀
Open source - DH
David Hendrickson@TeksEdgePost on X ·
🚨 Qwen4 is HERE! Best open-weight model (coming soon). 👀 But for us, the most important sentence in today's technical blog is at the very end! 👉"Smaller models in the family are coming to open source, built on the same lineage and trained with the same generation of techniques." 👈 Qwen4-27B, anyone? 🎉 This is Qwen4-Max! Stats 🧠 2.4T backbone parameters ⚡ 71B activated per token 💾 Additional 328B N-gram embedding parameters 📚 1 MILLION token context 👁️ Native vision 🤖 Stronger long-horizon agents And Qwen has changed the architecture. 👉 Gated DeltaNet + Qwen Sparse Attention 👉 4 parallel gated residual branches 👉 Context-based N-gram embeddings Qwen says its new base model performs better across Knowledge, Code, QA and STEM while activating 25% fewer parameters than Qwen3.8-Max-Base. Now look at the benchmark improvements. Qwen3.8-Max → Qwen4-Max 💻 DeepSWE v1.1 69.3 → 75.7 🤖 Agents' Last Exam 27.9 → 46.7 ⚙️ AutomationBench-AA 56.2 → 72.5 🏥 HealthBench Professional 39.6 → 60.0 On DeepSWE 🟣 Qwen4-Max → 75.7 ⚫ Kimi K3.1 → 75.5 🟢 GPT-6.1 Sol → 75.2 🟠 Claude Opus 5.5 → 74.2 BUT here's what REALLY interests me. Qwen4-Max is getting MORE work done with FEWER tokens. Terminal-Bench 4.0: 💻 Score: 38.9 → 48.5 📉 ~48–49% fewer tokens Work360: 📊 Score: 47.74 → 52.69 📉 24–35% fewer tokens 💰 Average cost per task: $4.43 → $1.67 That's a 62% reduction in cost per task in Qwen's evaluation. API pricing: 💰 Input: $1.50/M tokens 💰 Output: $4.50/M tokens 👈 💰 Cached input: $0.075/M tokens Now think about what this means for Local AI. We've spent months squeezing more tokens per second out of our RTX 3090s, 5090s, Strix Halo boxes, and Macs. But what if our next local model simply needs half as many generation tokens to complete the job? That's what I want to see tested on the smaller Qwen4 models. Qwen4-Max's API is live today. No downloadable Max weights announced. 💥 But Qwen has officially confirmed smaller open-weight models are coming. Give us Qwen4-27B! 🔥 Links in reply.
Open source - QW
QwenCloud@qwen_cloudPost on X ·
📢 Meet Qwen4-Max, your new AI teammate for work, creativity, and discovery! Qwen4-Max is built on a new MoE architecture with native vision and a 1M-token context window. Highlights: - Outperforms Qwen3.8-Max with up to ~50% fewer tokens, while average cost per task drops over 60% in our internal evaluation. - Advances real-world productivity through greater proficiency with professional tools, stronger long-horizon execution, and higher-quality deliverables. - Handles real tasks, including 3D modeling, game development, manufacturing, finance, law, healthcare, and frontier scientific discovery. - $1.5/M tokens for input, $4.5/M tokens for output, and $0.075/M tokens for implicit caching — all lower than Qwen3.8-Max, with implicit caching down by 70%. The API is live on QwenCloud. try it now: https://t.co/XSPs2ic5c4 Token Plan: https://t.co/aP7QXKVNEX More to come! The open weights of smaller Qwen4 models will be released. Stay tuned. 👀
Open source - TE
TechmemeArticle ·
Alibaba says Qwen4-Max, which isn't open weight, beats Fable 5.1 and Kimi K3.1 Pro in coding benchmarks, and plans to release weights for smaller Qwen4 models (Luz Ding/Bloomberg) Luz Ding / Bloomberg : Alibaba says Qwen4-Max, which isn't open weight, beats Fable 5.1 and Kimi K3.1 Pro in coding benchmarks, and plans to release weights for smaller Qwen4 models — Alibaba Group Holding Ltd. launched a new flagship AI model, claiming performance that rivals Anthropic PBC and OpenAI in China's latest challenge to US leaders.
Open source - TE
Techmeme@TechmemePost on X ·
Alibaba says Qwen4-Max, which isn't open weight, beats Fable 5.1 and Kimi K3.1 Pro in coding benchmarks, and plans to release weights for smaller Qwen4 models (@luzdingyu / Bloomberg) (Visit Techmeme dot com for the link and full context!)
Open source - TN
The New Stack@thenewstackPost on X ·
After opening Qwen3.8-Max, Alibaba is back to its old playbook: Qwen4-Max is API-only. But smaller Qwen4 models will eventually get open weights. https://t.co/H9CrlEQYOU
Open source - AA
Artificial Analysis@ArtificialAnlysPost on X ·
Alibaba has launched Qwen4 Max, gaining 9 points over Qwen3.8 Max on the Artificial Analysis Intelligence Index and landing 3 points behind Kimi K3.1 Pro at ~11% lower Cost per Task Qwen4 Max, using xhigh reasoning effort, scores 43 on the Intelligence Index, 9 points ahead of Qwen3.8 Max (xhigh) and 3 points behind Kimi K3.1 Pro (max, 46) Key takeaways: ➤ Qwen4 Max improves on every evaluation in the Index vs Qwen3.8 Max (xhigh, 34): HLE-Diamond +21 points (24% to 45%), AA-Omniscience +18 points, AutomationBench-AA +17 points, CritPt v2 +13 points, Terminal-Bench-Science +11 points, Terminal-Bench 4.0 +9 points, GDP.pdf +3 points, FrontierCode 2.0 +3 points and AA-Briefcase +82 Elo. ➤ Qwen4 Max costs $3.27 per Intelligence Index task, ~3x less than Qwen3.8 Max ($10.02) and ~11% less than Kimi K3.1 Pro ($3.68): This is driven by 25% lower per-token pricing than Qwen3.8 Max, 70% cheaper cache hits and lower token usage. Tencent Hy4 costs ~3x less per task ($1.03) than Qwen4 Max but scores 8 points lower on the Index. ➤ Qwen4 Max uses 39% fewer output tokens per task than Qwen3.8 Max: ~105k output tokens per Intelligence Index task vs ~171k for Qwen3.8 Max, ~72k for Kimi K3.1 Pro and ~78k for Tencent Hy4. Qwen4 Max uses fewer tokens, while increasing 9 points on the Intelligence Index ➤ Improvements in AA-Briefcase (knowledge work): On AA-Briefcase, our evaluation of agentic work across real business files, Qwen4 Max reaches 1686 Elo vs 1674 for Kimi K3.1 Pro and 1446 for Tencent Hy4. ➤ Qwen4 Max trails Kimi K3.1 Pro on Terminal-Bench 4.0 and Tencent Hy4 on FrontierCode 2.0: Qwen4 Max scores 48% on Terminal-Bench 4.0 vs 67% for Kimi K3.1 Pro and 37% for Tencent Hy4. On FrontierCode 2.0, @cognition’s private evaluation of real-world coding tasks, it scores 26%, level with Kimi K3.1 Pro (26%) and behind Tencent Hy4 (31%). Key model details: ➤ Context window: 1M tokens ➤ Multimodal: Text and image input with text output ➤ Pricing: $1.50/$4.50 per 1M input/output tokens on Alibaba's first-party APIs, with a $0.075 cache hit price. This is lower than Qwen3.8 Max across the board ($2.00/$6.00, with a $0.25 cache hit price) ➤ Availability: @Alibaba_Qwen 's first-party APIs
Open source - TE
Techmeme@TechmemePost on X ·
Alibaba releases Qwen4-Max, its new flagship 2.4T-parameter MoE model with a 1M-token context window, saying it beats Qwen3.8-Max with up to ~50% fewer tokens (Qwen) (Visit Techmeme dot com for the link and full context!)
Open source - TE
TechmemeArticle ·
Alibaba releases Qwen4-Max, its new flagship 2.4T-parameter MoE model with a 1M-token context window, saying it beats Qwen3.8-Max with up to ~50% fewer tokens (Qwen) Qwen : Alibaba releases Qwen4-Max, its new flagship 2.4T-parameter MoE model with a 1M-token context window, saying it beats Qwen3.8-Max with up to ~50% fewer tokens — Today, we are introducing Qwen4-Max, your new AI teammate for work, creativity, and discovery.
Open source